Together AI Launches Post-Training Service for Custom Model Development
Together AI has unveiled Together Post-Training, a new service designed to empower developers in building and customizing their own AI models with unprecedented flexibility and efficiency. This platform allows users to shape models from scratch using either environment rewards via Reinforcement Learning (RL) or supervision data via Supervised Fine-Tuning (SFT), abstracting away the complexities of underlying infrastructure.
Flexible Model Shaping
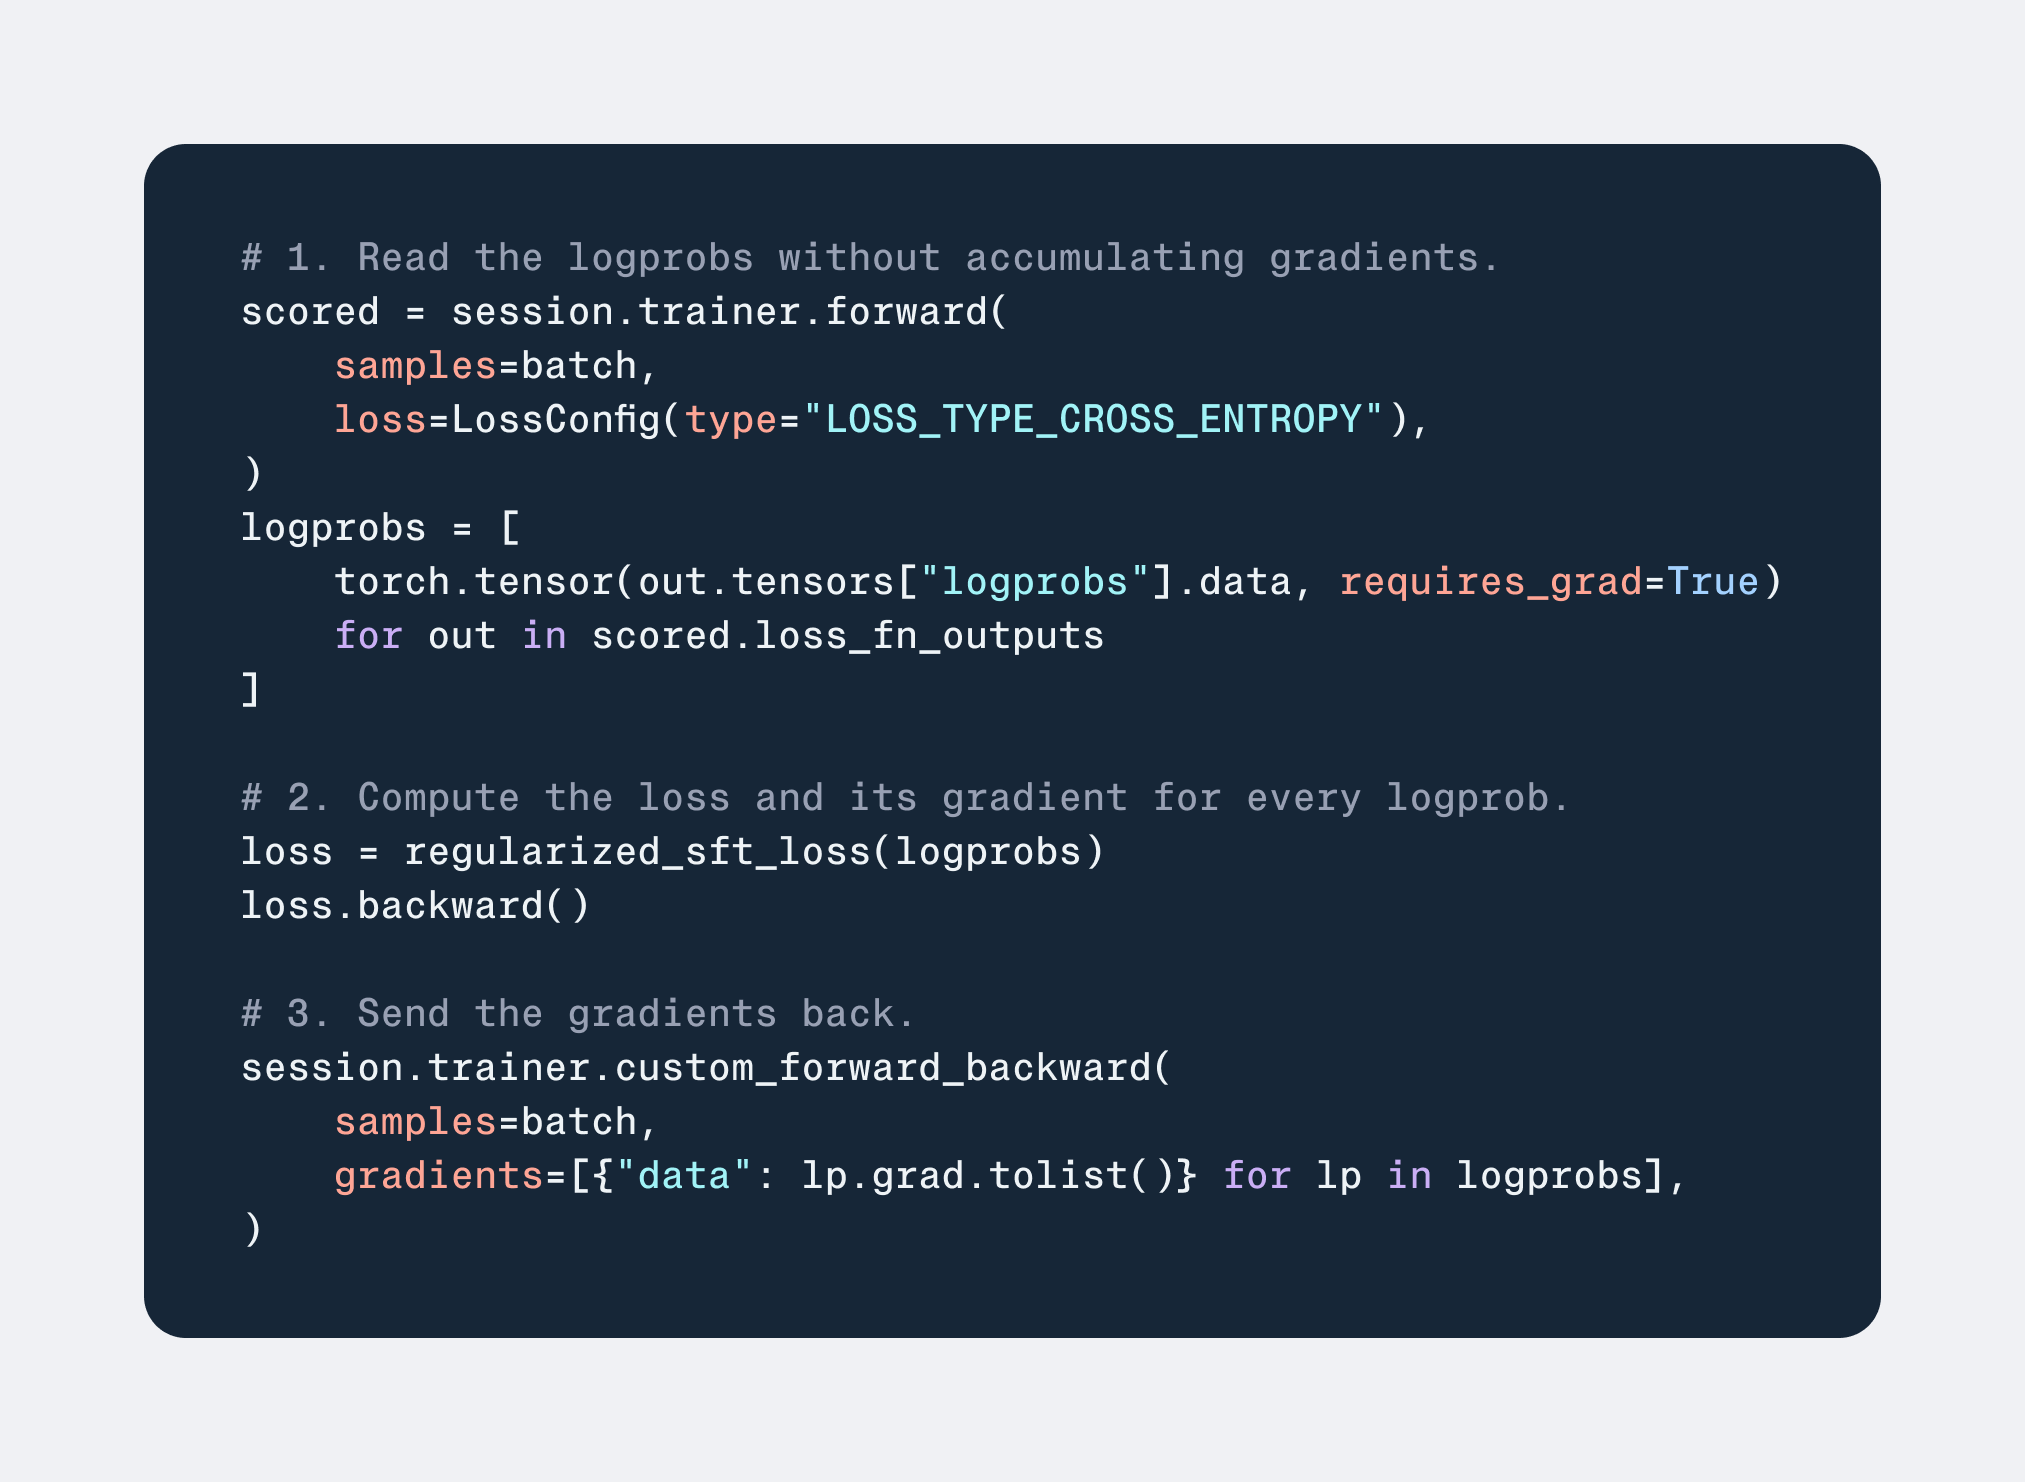
The core value proposition of Together Post-Training lies in its ability to provide users with complete control over the training loop. Unlike previous fine-tuning services, this new offering allows developers to define their own training processes, data, environments, and agentic harnesses. The service supports various training methods, including LoRA training with shared GPU capacity and full-weight experiments for select models. Each experiment runs on dedicated Model Resources, ensuring no competition with other users for GPU allocations, which is crucial for tasks requiring full-weight fine-tuning. The platform also offers asynchronous RL for high GPU utilization and supports custom training objectives by allowing users to send their computed gradients to the Trainer.
Addressing the Custom Model Demand
In 2026, the trend towards training custom AI models for specific workloads is accelerating, driven by the need for cost reduction and improved task-specific performance. Many organizations are moving beyond prompt engineering to train specialized agents that can match the quality of frontier models at a fraction of the cost and runtime. Together Post-Training aims to bridge the gap for companies that find the investment in post-training infrastructure and expertise prohibitive. The service handles the complex optimizations and infrastructure, allowing researchers and domain experts to focus on their core tasks while Together manages the underlying systems.
Quality, Performance, and Efficiency
Together AI emphasizes that the best training stack is the one that gets you the best model. The Together Post-Training service prioritizes the quality of output models by meticulously optimizing training and inference engines to eliminate policy drift caused by numerical mismatches. Leveraging years of research in inference products, the rollout engines are highly optimized, employing techniques like intelligent caching and routing for multi-turn agents. On the training side, optimized parallelism and sequence packing enhance speed for both SFT and RL steps. The service is designed for cost-efficiency, with users sizing experiments to their specific needs and paying only for what they use. For multi-LoRA experiments, several can share a single model resource, reducing overall costs, especially at scale.
Optimized Deployment and Getting Started
Post-training, Together Post-Training facilitates optimized deployment. Its Dedicated Model Inference service supports multi-LoRA adapter serving, allowing multiple adapters to be swapped within a single GPU deployment, thereby lowering serving costs. The platform ensures that trained checkpoints retain quality even after conversion for high-throughput production, including transitions to lower precision formats like FP4. To get started, users can install the latest Together SDK and consult the provided documentation and cookbooks, which offer examples for various training scenarios. For users migrating from services like Tinker API, a simple one-line code change is available. Early access partners like Deel, Jack & Jill, and Collinear AI have provided positive feedback, highlighting the platform's flexibility, efficiency, and the collaborative support from the Together Research team.
Special Launch Offer
To encourage adoption, Together AI is offering Together Post-Training at a reduced price of $9 per GPU-hour of B200 usage for the first eight weeks. For organizations seeking a partnership, Together AI's forward-deployed engineers offer end-to-end support, assisting with model selection, data curation, training environments, evaluations, and shipping optimized endpoints.